AI doesn't have to sound like a computer. Too often, AI text reads like AI slop.
We're here to fix that.

Output Analysis Example Review

Before: “It is important to note that further review may be beneficial.”

After: “This needs another look.”

Use of context On topic
Answers the question Partly
Unnecessary wording Some
Tone Consistent
Measure Test where models underperform
Tune Teach them what to do
Preserve See what training actually changed
What We Do

Sometimes an answer looks impressive but is unusable.

A model can know the lingo and still miss the point, or it can use way too much jargon and produce text that is indecipherable or downright annoying. When this happens, you'll feel like you're wasting your time with AI, and for good reason.

Lala Labs studies how large language models actually work by scrutinizing how they read, what they understand, and how they differ from actual human beings.

We use that research to help businesses produce their own AI systems that actually work and actually produce usable outputs.

Where Models Fall Short
01

LLMs are trained to be generic

Popular AI systems try to do everything for everyone, and as a result their outputs are far too generic to be useful for a cutting-edge company like yours. A useful answer often depends on tacit knowledge and instincts that your team takes for granted. The AI needs enough of that context to make a sound judgment. We help you inject that judgment into your AI.
02

You need to know why it went wrong

Giving a model more information won’t help if it doesn't understand what it's reading. We research the fundamentals of how LLMs work to give its understanding of inputs more dimensions. The end result is an AI that is more fluent, more nuanced, and feels more like a real co-worker than an irritating robot.

03

Words are important

We are a group of professional linguists, analysts, and data scientists who use our expertise analyzing language and communication. We do this so that we can evaluate and improve model output at the level of the words produced, which allows us to tweak outputs to your specifications and needs.

Products And Services

What we build and advise on

We help with model development from an initial review through deployment. We also build tools for working with AI-generated text and integrating LLMs into larger enterprise workflows.

Advisory And Implementation

Put your knowledge to work in a model

Advisory

Help with pre-training, post-training, retrieval, and deployment, including decisions about what vendors are best for you, what you should be building and how to test it most easily and at lowest cost.

Custom Learning Environments

Training tasks and feedback based on the work you need the model to do.

Domain Expertise

Train models on material from your field so they can apply it to real-world decisions your team faces on a daily basis.

LALA Benchmark

Our work begins with the Literature and Linguistics Analysis Benchmark (LALA), a sophisticated research framework and analytical tool developed by professors of linguistics at Oxford, Birmingham, and other institutions around the world that identifies the limitations LLMs face in interpreting and producing text.

Our work ends with custom benchmarks designed for your needs.

Custom Benchmark

We can produce evaluations built around your business, with enough detail to show where an AI falls short and how to make it do what you want it to do, instead of what an AI company tells you it should do.

Token-To-Information Optimizer

We can help your existing LLMs and AI infrastructure work more efficiently, reducing unnecessary text in model responses and agent instructions while checking that essential information survives. This saves on how many tokens your enterprise burns and, more importantly, saves on the time your team needs to spend analyzing what your AI has given them.

Language Systems

Make model output easier to use.

SAM

Semantic Analysis Matching examines how a model interprets the terms and distinctions in your field, helping you to train your own custom system on your own material.

AI2H

AI-to-human text generation edits model drafts for more natural writing. It cuts repetitive phrasing and adjusts the prose for its intended reader.

TAD

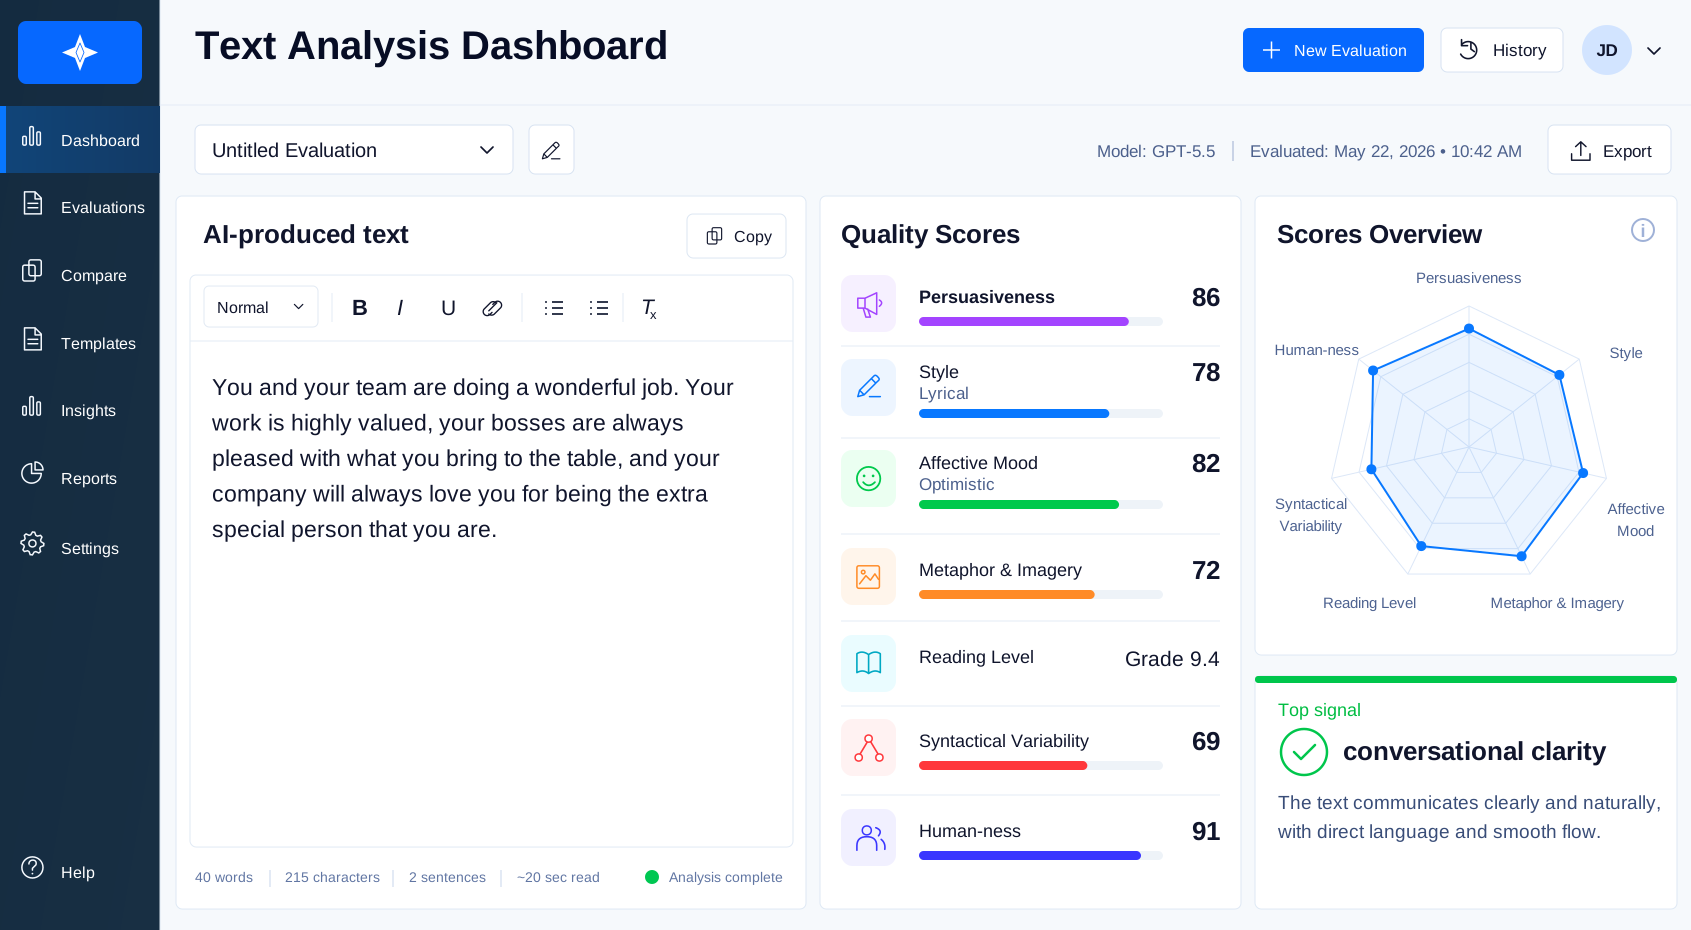
The Text Analysis Dashboard lets you review AI writing for clarity, tone, style, and how well it suits its audience, giving you a platform to adjust textual outputs on the fly.

Consulting and Advisory

Work out whether AI is useful here.

Enterprise Solutions

Show us where the model gets stuck

Show us an AI response that didn’t work and explain what you wanted to see. We can investigate what happened and why, so your AI delivers what you want.

Discuss a model audit
TAD Text Analysis Dashboard product screenshot
TAD — Text Analysis Dashboard

Research

How well do language models understand language?

Our research examines how models interpret and use language. We look at individual abilities and error patterns, and we identify how they differ across models and stages of training to improve training process from initial corpus tokenization to fine-tuning.

01 / Understanding

Look closely at the answer

Can the model explain a passage’s meaning, including what the writer leaves unsaid? We examine its interpretation rather than taking a fluent answer at face value.

02 / Training

Examine what changes after training

Did more training actually improve the model in a way that's useful? We compare base and post-trained models to examine how training affects an AI's language abilities. An improvement on one task may come at the expense of another.

03 / Meaning

Test what happens when context matters

The same words can mean different things in different settings. We test whether models use the surrounding context to work out what a text should say.

Work With Lala Labs

What would you like your AI to do better?

Tell us what you’re trying to do and where the current results fall short. We’re eager to discuss how we can help.

Contact Lala Labs